LLM training is the multi-stage process of building a large language model. It begins with collecting and cleaning very large amounts of text and code, continues with pretraining, in which the model learns to predict the next token, and ends with tuning stages that teach it to follow instructions, behave safely and use tools. The process turns random numbers in a neural network into a system that can write, answer questions and reason about text. It requires large datasets, powerful computing hardware and careful evaluation, and it is the main reason why large language models have become possible.
History of LLM training
Early language models used counts of word sequences and were trained in minutes. Neural models in the 2010s were trained on single machines or small clusters. The transformer of 2017 made training highly parallel, and BERT and GPT in 2018 popularized pretraining on unlabeled text followed by adaptation. In 2020, OpenAI researchers reported scaling laws showing that loss falls predictably with model size, data and compute, which encouraged much larger runs such as GPT-3. In 2022, DeepMind’s Chinchilla study showed that many models were undertrained and that data should grow in proportion to model size. InstructGPT and ChatGPT in 2022 added instruction tuning and reinforcement learning from human feedback to make models helpful, and since then, training has expanded to include reasoning training, synthetic data, multimodal data and training for tool use.
Stages of LLM training
### 1. Data collection and preparation
Developers gather text from web crawls, books, scientific papers, code repositories, forums, encyclopedias and licensed or curated sources. The data is cleaned by removing duplicates, low-quality or machine-generated pages, personal information and harmful content, and by filtering for language and quality. Text is converted into tokens. See tokenization. The mix of sources and the quality of filtering have a large effect on the final model.
### 2. Pretraining
In pretraining, the model learns to predict each next token across trillions of tokens of text. The network, usually a transformer, has its parameters adjusted by backpropagation and an optimizer such as Adam, a form of gradient descent. The work is spread over thousands of accelerators using data, tensor and pipeline parallelism, and takes weeks or months. Teams monitor loss curves and restart from checkpoints when hardware fails. Pretraining gives the model broad knowledge and language skills, but it does not yet make it a helpful assistant.
### 3. Supervised fine-tuning and instruction tuning
The model is then trained on curated examples of prompts paired with high-quality responses written by people or generated and filtered by other models. See instruction tuning and fine-tuning. This teaches the format of helpful answers, how to follow instructions and how to hold a conversation.
### 4. Alignment and preference training
Human raters compare model answers, and their preferences are used to train a reward model or to directly optimize the model, as in reinforcement learning from human feedback and direct preference optimization. Variants use written principles, as in constitutional AI, or AI feedback to scale the process. The goal is to make answers more helpful, honest and harmless. Reasoning models add reinforcement learning on problems with checkable answers, such as mathematics and code.
### 5. Evaluation, safety testing and release
Developers test the model on benchmarks for knowledge, reasoning, coding and safety, run red-team exercises to look for harmful behavior and refine it. After release, they monitor use and update the model.
Compute, cost and energy
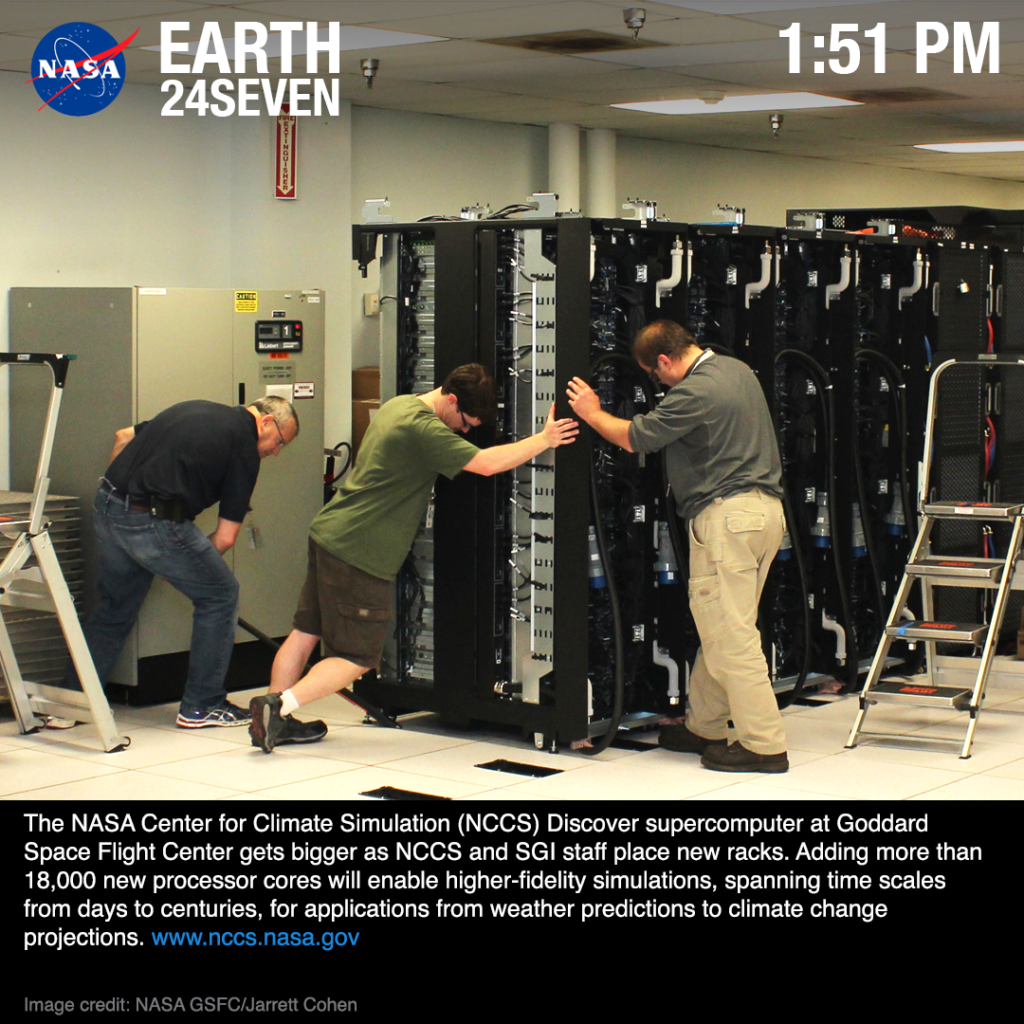
Frontier training runs consume enormous resources. A large run can use tens of thousands of graphics processors for months and cost tens to hundreds of millions of dollars, plus the expense of data, research staff and failed experiments. The energy used is substantial, and developers increasingly report efficiency efforts such as better hardware, lower-precision arithmetic, see quantization, and sparse mixture-of-experts designs that activate only part of the network for each token. Inference, the cost of serving users, often exceeds training cost over a model’s lifetime.
Challenges
- Data quality and quantity: high-quality text is limited, which pushes interest toward synthetic data, though over-reliance can cause model collapse.
- Copyright and consent: the use of copyrighted works for training is contested in courts.
- Privacy: models can memorize personal information from training data.
- Bias: training data reflects social biases that models may reproduce.
- Stability: very large runs can diverge or fail, requiring careful engineering.
- Evaluation: benchmarks may leak into training data and may not reflect real use.
Open and closed training
Some developers publish model weights and training details, enabling research and customization, while others keep them private for commercial or safety reasons. Smaller organizations typically do not train from scratch. They adapt open models with fine-tuning or low-rank adaptation, which updates only a small number of added parameters.
A worked example
A university team wants a model for scientific text. Rather than pretraining from scratch, which would cost millions, they start with an open pretrained model and continue pretraining on a filtered collection of open-access papers. They then fine-tune on question and answer examples written by domain experts and test the result on held-out questions. They publish a model card that describes the data, limits and intended use.
Hardware and parallelism
Training at this scale is as much an engineering problem as a research one. A model with hundreds of billions of parameters does not fit in the memory of one accelerator, so the work is split. Data parallelism gives each group of chips a copy of the model and a different slice of the batch, tensor parallelism splits individual matrix operations across chips and pipeline parallelism assigns different layers to different chips. Fast interconnects, careful scheduling and frequent checkpoints keep thousands of chips busy and let a run recover when a component fails. Mixed-precision arithmetic, which uses 16-bit or 8-bit numbers for most calculations, increases speed and lowers memory needs with little loss of quality.
Governance, documentation and safety
Responsible developers document training data sources, filtering steps, evaluation results and known limits in model cards and system cards. Some jurisdictions now require providers of general-purpose models to publish summaries of training content and to assess systemic risks. Safety work runs through the process, with filtering of data at the start, refusal and honesty training in the tuning stages and red teaming before release. Independent audits and shared evaluation suites help the public see how models behave, and incident reporting helps developers fix problems after deployment.
Future directions
Researchers are working on data-efficient training, better use of synthetic and curated data, training that rewards verifiable reasoning, continual learning that updates a model without full retraining and lower-energy hardware and algorithms. Another active area is making training transparent enough that outsiders can check claims about data, safety and capability.
Related concepts
Training ties together many ideas covered elsewhere, including embedding of tokens, the context window used during training and inference and the temperature setting that shapes sampling after training is finished.
FAQs
How long does it take to train an LLM? Frontier models take weeks to months on large clusters, while fine-tuning a small model can take hours on a single machine.
Why does training need so much data? The model must see many examples of language use to learn grammar, facts and reasoning patterns across many topics and styles.
What is the difference between training and inference? Training adjusts the model’s parameters, while inference uses the trained model to answer prompts.
More in Large Language Models
Key facts
- Training a large language model typically has stages of pretraining, supervised fine-tuning and preference-based alignment such as reinforcement learning from human feedback.1
- Scaling-law research found that model size, data and compute should be increased together for best results.2
- Frontier training runs use thousands of accelerators for weeks or months and consume large amounts of energy.3
Related concepts
Quick checkWhat are the main stages of training a large language model?Show answer
Data collection and preparation, pretraining to predict the next token, instruction tuning on prompt and response examples, and alignment with human preferences, followed by evaluation and safety testing.
Sources
- Ouyang et al., Training language models to follow instructions with human feedback, https://arxiv.org/abs/2203.02155
- Hoffmann et al., Training Compute-Optimal Large Language Models, https://arxiv.org/abs/2203.15556
- Patterson et al., Carbon Emissions and Large Neural Network Training, https://arxiv.org/abs/2104.10350
Editorially reviewed by Specialty Digest Editorial TeamLast reviewed November 17, 2026Researched and drafted with AI assistanceReport an issue